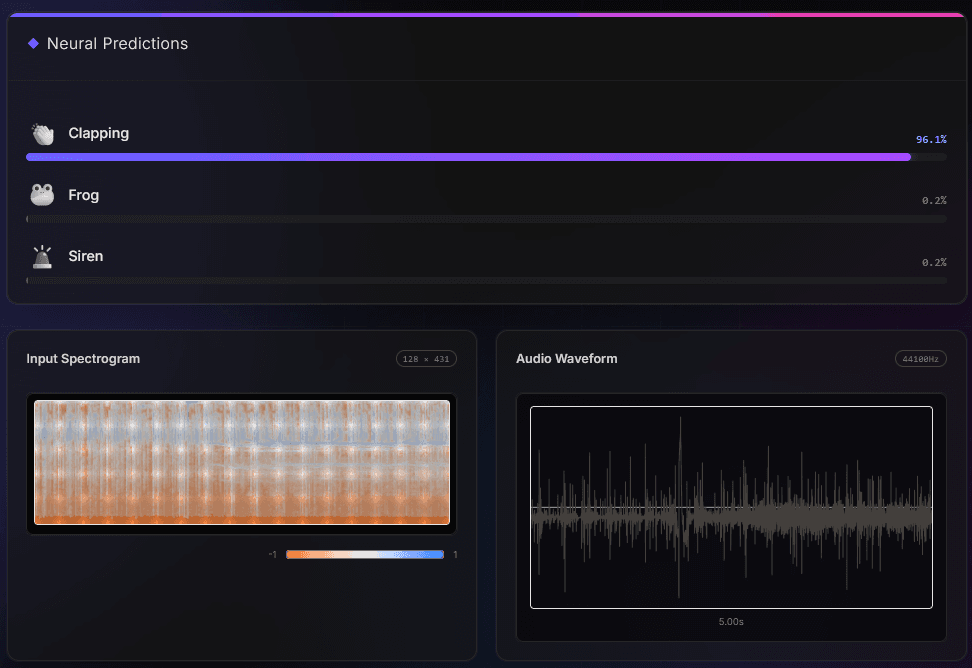
A CNN-powered audio classification and visualization engine. Classifies audio in real-time using PyTorch and TensorFlow, generates waveform visualizations with Librosa, and renders an interactive dashboard in Next.js.
Synapse Sound is a full-stack audio intelligence platform that combines deep learning with real-time signal processing. The core engine uses a convolutional neural network trained on the UrbanSound8K dataset, achieving 92% classification accuracy across 10 audio categories.
The system captures audio input, processes it through a feature extraction pipeline (Mel-frequency cepstral coefficients, spectrograms, chromagrams), and feeds it to the CNN for real-time classification. Librosa handles all DSP operations while PyTorch and TensorFlow power the inference engine.
The frontend is a Next.js dashboard with live waveform rendering, spectrogram visualization, and classification confidence meters. WebSocket connections ensure sub-100ms latency between audio capture and visual feedback.